


What is Boundary Value Analysis in Software Testing? A Complete Guide
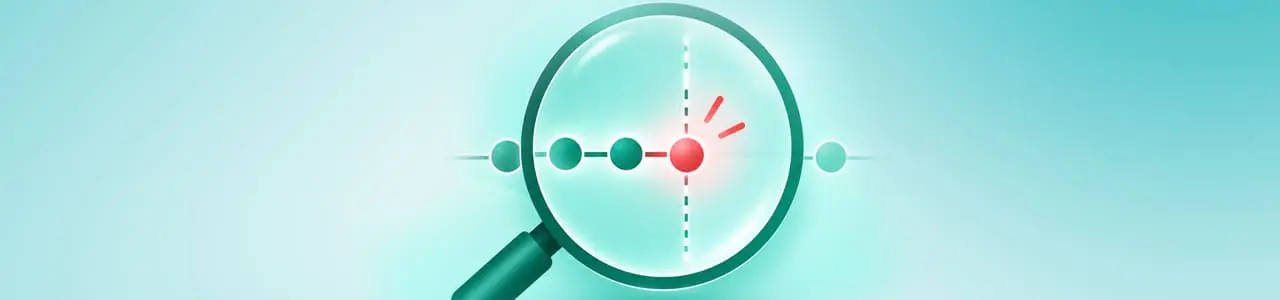
Boundary value analysis in software testing is a way of testing inputs right at the edges of allowed values. Instead of trying every possibility, you focus on the aspects most likely to break. If you’ve spent time debugging production issues, you’ve probably seen this pattern already. Systems usually behave fine in the middle, while problems show up at limits. That’s what this technique is built around.
Boundary value analysis (BVA) is a black-box technique that tests values at the edges of allowed ranges rather than sampling all in between. Bugs tend to cluster at limits, so a few well-chosen tests get identified a lot.
- Why it matters: Actual failures appear like a signup form rejecting age 18, a payment failure at the precise transaction limit, or an API breaking at its highest payload size.
- Examples: For an age range of 18 to 56, seven tests (17, 18, 19, 37, 55, 56, 57) replace dozens. A ₹1,000 to ₹10,000 banking limit is included by six values around each edge.
- Types of BVA: Normal tests only valid edges, while Robust adds invalid ones. Worst-Case checks combinations across several inputs, and Robust Worst-Case merges both. The 2-value variant halves the test count by checking only the boundary and the value just outside it, so it suits low-risk fields better than anything involving money, security, or compliance.
- Single fault assumption: Vary one input at a time while keeping others normal. The maximum count for tests is 4n + 1, where n is the number of variables.
- Pairing with equivalence partitioning: Partitioning decides what groups to test, and BVA decides where inside those groups. Using both gives better coverage for little extra effort.
- API testing: Boundaries also live in payload sizes, pagination limits, schema length constraints, rate limits, and numeric query parameters. These are easy to miss because no visible form field prompts a tester to check them.
- Common pitfalls: Teams often test only the valid side and treat BVA as enough on its own. Apply the single fault assumption to interactions between fields, or update stale boundary tests when requirements shift.
- Automation: Playwright and Cypress suit UI checks, Postman and Karate suit APIs, and schema-driven tools can derive limits from OpenAPI specs. ACCELQ is presented as a no-code option for reusing boundary logic across layers.
- Takeaway: The technique is easy, but applying it consistently is difficult. Strategic testing beats more testing.
What is Boundary Value Analysis, Why It Matters & Example
What is Boundary Value Analysis?
Boundary value analysis, or BVA, is a black-box testing approach in which you test values at the edges of a range rather than within it. So instead of testing 20 values, you might test just a handful as follows:
- The smallest allowed value.
- One just above it.
- Something in the middle.
- One just below the maximum.
- The maximum itself.
That’s usually enough to expose most input-related issues.
Why Boundary Value Analysis Matters
The idea that everything should work fine across the entire range looks good in theory. In reality, boundaries are where logic tends to fall apart. Think about everyday scenarios:
- A signup form rejecting age 18 even though it should allow it.
- A payment system failing at the exact transaction limit.
- An API throwing errors when payload size hits the upper threshold.
These aren’t rare edge cases; instead, they’re common failures. That’s why teams rely on boundary value testing to detect problems early without writing a huge number of test cases.
Boundary Value Analysis Example
Say an application accepts ages between 18 and 56. Instead of testing every age, you focus on key points:
| Case | Value | Expected |
|---|---|---|
| Below minimum | 17 | Reject |
| Minimum | 18 | Accept |
| Just above | 19 | Accept |
| Middle | 37 | Accept |
| Just below max | 55 | Accept |
| Maximum | 56 | Accept |
| Above maximum | 57 | Reject |
Seven tests instead of dozens. Here’s a case where boundary value analysis testing carries real weight. Consider a banking app with a transaction limit between ₹1,000 and ₹10,000. You don’t need to test all numbers. You can test:
- 999
- 1000
- 1001
- 9999
- 10000
- 10001
That’s where failures actually happen.
Types of BVA & The Single Fault Assumption
Normal Boundary Value Analysis
This version accepts only valid inputs. You can test the edges that are supposed to work. Good for basic validation when you’re confident the system handles invalid input elsewhere.
Robust Boundary Value Analysis
This type goes one step further. You include invalid values as well, like:
- One below minimum.
- One above maximum.
It is closer to how real users behave, so most teams use it in practice.
Worst-Case Boundary Value Analysis
Normal and Robust BVA vary one input at a time. Worst-Case BVA drops that assumption and tests combinations of boundary values across many inputs at once.
This matters when inputs interact in a shipping form, where weight and dimensions are both near their limits simultaneously. Testing each field individually can miss a failure that only appears when both are at their extremes.
Robust Worst-Case Boundary Value Analysis
This combines the two ideas: it tests combinations of boundary values, and it includes invalid values in those combinations.
It provides the most thorough coverage of the four; still, it also generates the most test cases. So it’s usually reserved for high-risk, tightly coupled input fields rather than applied everywhere by default.
2-Value Boundary Value Analysis
The examples above use 3-value BVA (i.e., testing the boundary plus 1 value on either side (17, 18, 19). But 2-value boundary value analysis is a leaner variant (i.e., instead of 3 points per boundary, you can test only 2: the boundary value and the value immediately outside, 17 and 18, or 56 and 57, skipping the inside value).
It reduces the test count in half, which is useful when a team has a lot of boundaries to cover within less time. The trade-off is coverage: 2-value BVA assumes that if the system handles the boundary and the value past it correctly, the value inside is safe too. That assumption often holds in low-risk fields, but it’s not something to default to for inputs tied to money, security, or compliance; those are exactly the fields worth spending the extra test case on.
What is Single Fault Assumption in BVA?
Things get tricky when you have multiple inputs. Testing every combination quickly becomes unrealistic. So, testers use something called the single fault assumption. The idea is simple: you vary one input at a time while keeping the others normal.
Boundary Value Analysis Formula
Maximum test cases = 4n + 1. Here, n is the number of variables. Suppose you need to validate a date:
- Day (1–31)
- Month (1–12)
- Year (1900–2000)
It is not required to test all combinations. You can change just one input while leaving the others as they are. That keeps testing manageable without losing coverage.
Equivalence Partitioning and Boundary Value Analysis
A common question when learning equivalence partitioning software testing is how it relates to BVA. Equivalence partitioning and BVA solve slightly different problems, but they’re most effective when used together.
Equivalence partitioning groups inputs into categories. Boundary value analysis focuses on the edges of those categories. Simply put, that’s what equivalence partitioning and boundary value analysis are, at a glance. One narrows down what to test, while the other pinpoints exactly where to test it.
Difference in simple terms
| Technique | What it does |
|---|---|
| Equivalence Partitioning | Tests one value per group |
| Boundary Value Analysis | Tests edge values |
Example: If valid input is 6 to 10 characters:
- Partitioning checks one valid and one invalid value.
- BVA checks 5, 6, 10, and 11.
Using both gives better coverage without additional effort.
Boundary Value Analysis for API Testing
Most BVA examples stop at form fields such as age, password length, and transaction amount. But APIs have their own boundary conditions, and they fail as predictably at the edges. A few places to look:
-
Payload size limits: If an endpoint accepts a JSON body up to 1 MB, test at 1 MB minus a byte, exactly 1 MB, and 1 MB plus a byte. Many services silently truncate or return a generic 500 instead of a clean 413 response at this exact boundary.
-
Pagination and page-size parameters: If page_size accepts 1 to 100, test 0, 1, 100, and 101. A surprising number of APIs accept page_size=100000 and return an unbounded, slow response instead of rejecting it.
-
String and array length in schemas: A maxLength: 255 field in an OpenAPI spec should be tested at 254, 255, and 256 characters. The same applies to array fields with maxItems constraints. One entry over the limit is often accepted because validation was enforced only on the frontend.
-
Rate limits: If a client is capped at 100 requests per minute, the boundary is not just at 100. It is the 100th and 101st request within the same rolling window. Testing this requires controlling timing, not only request count, which is why rate-limit boundaries are often skipped.
-
Numeric query parameters: Limit, offset, min_price, and max_price behave like the classic age-field example, but they are easy to overlook because they do not appear in a UI form for testers to validate visually.
The technique does not change. What changes is where the boundaries are present in a schema, a rate-limiter config, or a query parameter definition instead of a visible input box. That also means API boundary defects are easier to miss during manual testing, since there’s no field to check; they need to be pulled from the API contract tests.

Limitations in Boundary Value Testing
BVA in software testing is useful, but it’s not a complete solution, and a lot of the value gets lost through a handful of repeated mistakes.
- It doesn’t handle relationships between inputs well. If two values depend on each other, like a discount tier that shifts based on both order value and customer type. Testing them individually can miss the interaction. This is exactly where Worst-Case BVA earns its extra test cases; skipping it here is the most common gap.
- Teams only test the valid side. Normal BVA alone (min, max, and the values just inside them) looks complete but quietly skips how the system handles the invalid side. If 57 isn’t tested alongside 56, a system that “accepts” 57 anyway goes unnoticed until production.
- BVA gets treated as sufficient on its own. It’s a strong technique for input validation, but it won’t catch logic errors that sit outside that validation layer: a workflow bug, a race condition, a permissions issue. Teams that stop at BVA and call testing “done” are testing one layer, not the system.
- Boundaries get hardcoded once and never revisited. Limits change: a price cap moves, a character limit gets extended for a new locale, but the boundary test cases are often written once during initial development and forgotten. Stale boundary tests can pass while validating limits that no longer match the real requirement.
- Interdependent fields get tested with the single fault assumption when they shouldn’t be. The single fault assumption is a scoping tool to keep test cases manageable, not a universal default. Applying it to known fields to interact defeats its own purpose.
Applying BVA: Process, Automation & How ACCELQ Fits In
If you’re implementing BVA from scratch, the process is:
- Identify the input range
- Mark minimum and maximum values
- Pick values around those limits
- Create test cases
- Validate results
In agile environments, testing is continuous, and BVA is suitable because it’s fast and focused. Teams often include boundary tests during sprint development, as part of regression suites, and in CI/CD pipelines to capture issues early instead of after release.
Manually finding edge cases works, but it doesn’t scale properly. Once an application grows, inputs multiply, rules change, and it gets harder to tell if coverage is still complete. That’s the point where boundary testing usually starts slipping, not because teams don’t understand BVA, but because keeping it consistent across releases becomes difficult.
This is where automation helps. Modern tools can detect input ranges, generate boundary scenarios from a schema or spec, and automatically run them across builds, instead of relying on someone to remember and update a spreadsheet of edge cases.
SUGGESTED READ - 12 Top Rated Test Automation Tools in 2026: Compared & Reviewed
Which tools are best for automating boundary testing?
It depends on where the boundary resides. Yet some of the best tools are:
- UI-level boundaries: Playwright or Cypress can drive boundary values through the interface, though someone still has to define them.
- API-level boundaries: Postman or Karate are common choices for scripting boundary test data directly against endpoints.
- Schema-driven boundaries: Tools that can read an OpenAPI/Swagger spec and automatically derive min, max, and maxLength constraints save the step of manually retyping limits into test scripts.
- No-code, cross-layer boundaries: Platforms like ACCELQ let testers define boundary logic once in plain terms and reuse it across UI and API tests without maintaining separate scripts for each.
The choice is about how much of the boundary logic you want residing in code versus in a reusable, no-code test design.
How ACCELQ fits into boundary testing
ACCELQ helps more with consistency than anything else. Instead of writing separate scripts for every edge case, you define the logic once and reuse it when needed. The boundary conditions become part of the test design, not something pointed out later.
The no-code approach also changes who can contribute. You don’t need a developer to translate every boundary scenario into code; testers can define what needs to be validated in plain terms and move on.
Where it gets interesting is maintenance. Normally, boundary-heavy tests are the first to break when something changes. With ACCELQ, those updates don’t always mean rework, since the system adjusts based on how elements behave rather than just where they’re located.
Autopilot adds another layer by not replacing testing; instead, it helps you surface gaps and sometimes even point out edge cases a tester didn’t think of, reinforcing what they already knew. Both are useful, and at that point, boundary testing stops being a one-time checklist and starts becoming part of how the system is validated continuously.
Conclusion
Boundary value analysis is simple, but it’s not basic. Many teams understand it, but few apply it well.
Most bugs don’t come from complex logic; rather, from small assumptions that break at the limits. A value outside the range and a condition that wasn’t handled properly are exactly what BVA is meant to catch.
The tricky part isn’t understanding the technique. It’s using it consistently across form fields and API contracts alike, without making testing overly burdensome.
Teams that get this right usually aren’t doing more testing. They’re just testing strategically. Catching edge-case bugs shouldn’t depend on manual effort. It’s time to make testing scalable. Get in touch with our team.
FAQ's
What is boundary value analysis in software testing?
Boundary value analysis is a software testing technique that validates input values at the edges of defined ranges. Defects appear more often at these boundary points rather than in the middle of a range.
What is equivalence partitioning and boundary value analysis?
Equivalence partitioning splits inputs into groups and tests one value per group. Boundary value analysis focuses on testing values at the edges of those groups, where failures are more likely to occur.
How does boundary value analysis improve software testing accuracy?
Boundary value analysis improves testing accuracy by focusing effort on input values that are most likely to expose defects. It checks range edges instead of spending equal effort across every possible value. Incorrect comparison operators, such as using > instead of >=, are commonly detected at boundaries.
Can you explain the process of boundary testing in simple terms?
Find the smallest and largest values an input allows. Then test the values at those limits and just outside them. For example, if an age field accepts values from 18 to 56, test 17 and 57 along with the valid boundary values to confirm the limits work correctly.
What are the common mistakes to avoid during boundary value analysis?
Common mistakes include testing only valid boundaries while skipping invalid ones, treating BVA as sufficient without covering workflow or logic-level defects, applying the single fault assumption to inputs that interact, and leaving old boundary test cases unchanged after business rules or limits change.
Which tools are best for automating boundary testing?
It depends on the layer being tested. Playwright works well for UI-level boundary fields; Postman is common for API-level boundaries like payload size or rate limits. Agentic no-code platforms like ACCELQ let teams define boundary logic once and reuse it across UI and API tests without maintaining separate scripts.
What are the types of boundary value analysis?
The main types are Normal BVA, which tests only valid boundaries; Robust BVA, which adds invalid boundary values; Worst-Case BVA, which tests combinations of boundary values across multiple inputs; and Robust Worst-Case BVA, which combines both approaches for maximum coverage.
How does boundary value analysis apply to API testing?
Boundary value analysis applies to API testing through payload size limits, pagination parameters, schema-defined string or array length constraints, and rate limits. Testing values just inside and outside these thresholds helps identify validation gaps that may not appear in the UI.
What is 2-value boundary value analysis?
2-value boundary value analysis tests the boundary itself and the value immediately outside it, such as 56 and 57. It reduces the number of test cases compared to traditional BVA but is better suited for lower-risk fields because it does not confirm the value just inside the boundary.


You Might Also Like:
 Locators in Test Automation: A Deep Dive
 OCR Test Automation: How to Hit Peak Accuracy & Speed?
 Low-Code Automation Platform: Why Enterprises Are Shifting